 Roman Hromenkov, founder · Tallinn
Two of our own automations ran exactly as written and quietly ran up a bill: 840 hours of build machines and a nightly AI check nobody read. What we changed, and the two questions we now ask before anything runs on a schedule.
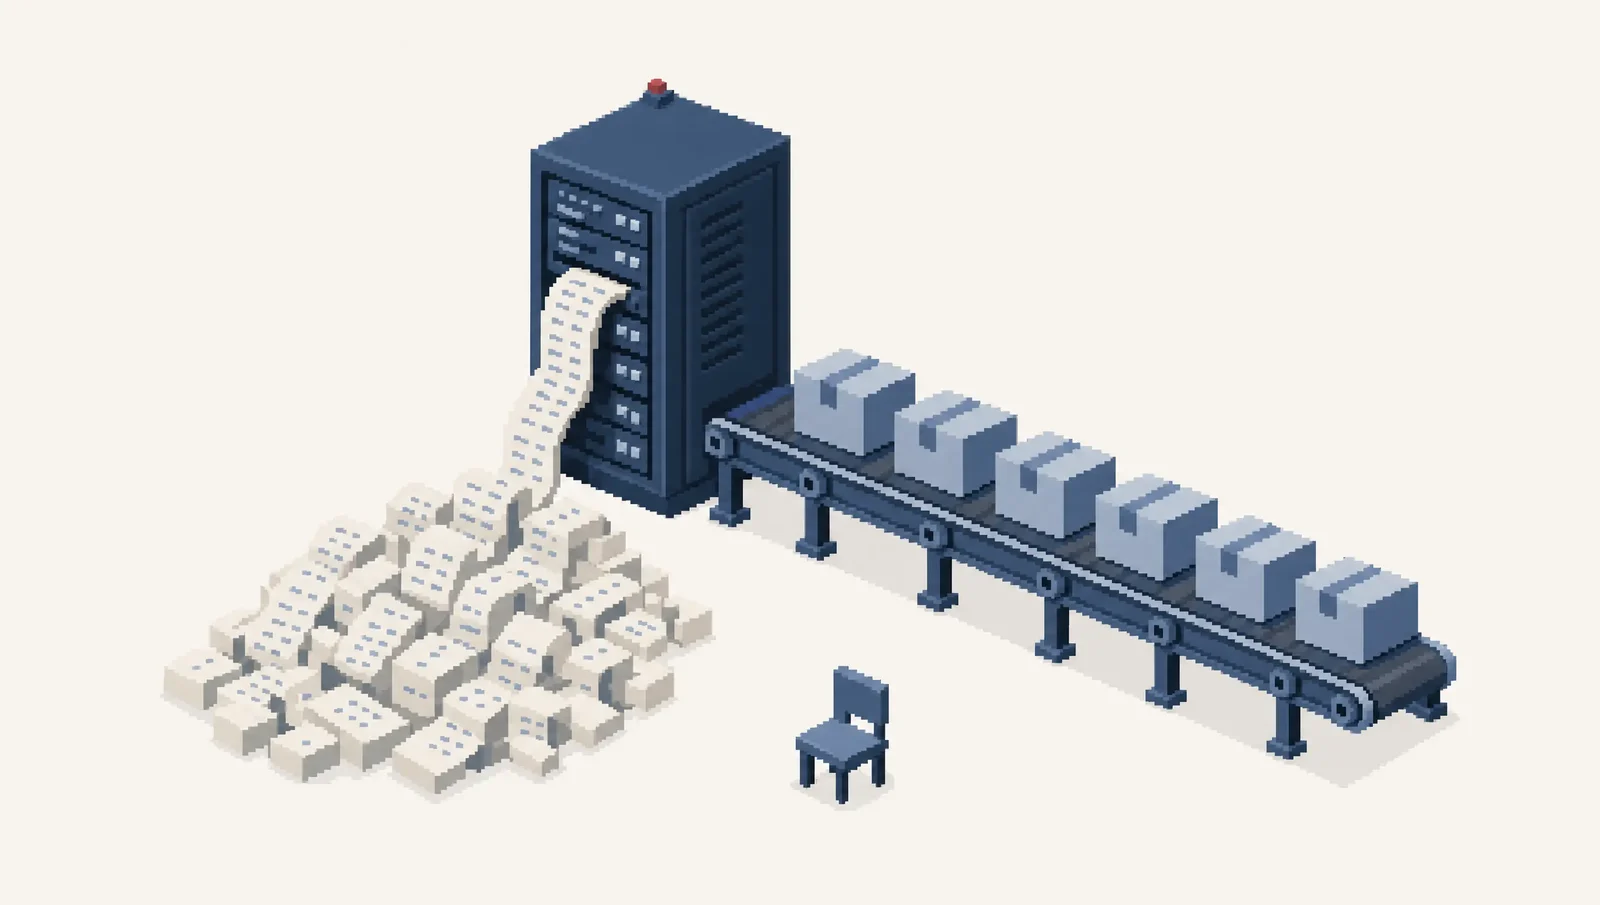
Automation has a property that people rarely mention when they sell it: once it works, nobody looks at it. That is the point – and it is also how a process can run perfectly, exactly as written, and cost money every hour without anyone noticing.
This summer it happened to us twice, on our own projects. Neither was a bug in the usual sense. Both were found by a person looking at a bill, not by an alert.
Case one: 12,620 rebuilds of the same code
We run a small cloud service that watches markets and news and sends a morning digest. It keeps a bit of memory between runs – what it has already seen, what is queued – and it saved that memory the simplest possible way: as a commit to its own code repository.
The catch was where that repository led. It was wired to our hosting, and every new commit there means "build and deploy the site again". So every time the service remembered something, the hosting provider rebuilt and redeployed a website whose code had not changed.
The numbers, from 1 June to 27 July:
- 12,620 commits, of which 22 touched actual code. The rest were the service saving its memory.
- About 270 production deploys a day, each one byte-for-byte the same as the last.
- 840 hours of build machine time – 90.7% of all build hours on the account.
- The news check alone ran every 15 minutes and wrote two commits each time: 72% of the waste.
22 changed code 12,598 only saved state
Roman found it by opening the usage chart. Nothing had failed, so nothing had alerted.
The fix took two parts. The service's memory moved to a separate repository that is not connected to any deploy. And the hosting now runs a short check before every build: if nothing but saved state has changed since the last successful deploy, the build is skipped. When the check is unsure, it builds anyway – a wasted build is cheaper than a missed release. Since then, idle builds: zero.
Case two: a nightly AI check that was red every night
Our farm product has an AI assistant, and we had set up a nightly evaluation: a script asks the assistant a fixed set of questions, scores the answers, and fails if quality drops. It is a good idea. It is how you notice that a model change made the answers worse.
For twelve nights in a row it failed. Same failure, same scores. The thing it existed to catch – answers getting worse over time – never happened: every night it reported that drift was within the threshold, and every night it went red anyway on a few individual questions whose bar was set too high.
Nobody reacted, because a check that is always red stops being read. Meanwhile each run called a paid model: about $1.45 a night, roughly $43 a month – and that was the entire AI bill for that project.
The reason we switched it off was one sentence from Roman: we have no users yet. Between two nights nothing had changed – no new code in that part of the product, no real conversations. A test that compares the product with itself, when the product hasn't moved, measures nothing.
We switched it off in two places: in the CI dashboard, and in the file itself, with the reason, the numbers and how to turn it back on written at the top. A switch that lives only in a dashboard disappears the next time someone rebuilds the setup – and they turn it back on, because they don't know why it was off.
We kept the evaluation itself. It still runs whenever someone changes the assistant's code: then something has changed, and the run is worth paying for.
One more thing came out of it. Under the permanent red, the evaluation had been showing a real problem: creating a farm activity by talking to the assistant almost never worked. Nobody had seen it, because everything was red. A check that always fails doesn't just cost money – it hides the one finding that matters.
What the two cases have in common
Both mechanisms did exactly what they were built to do. Nobody made a mistake you could point at in a code review. What was missing was a question nobody asked when the schedule was set up.
So now we ask two questions before anything runs on its own:
- Who reads the result? A name, not "the team". If nobody reads it, it is not monitoring – it is a subscription.
- What changes between two runs? If the honest answer is "nothing", the schedule is wrong. Run it when something changes: a new release, new data, a real user.
And one habit for the bill itself: look at it once a month, by project. A person spends unevenly. A flat line, the same amount every day, is almost always a schedule – and you should be able to name which one.
If you run automations
You don't need to read code to catch this. Ask whoever built your automations for three things:
- a list of everything that runs on a schedule, with who reads each result;
- the monthly cost of each one, including the services it calls;
- where the "off" switch lives – in the code, with a reason, or only in someone's dashboard.
If any of the three takes more than a day to answer, that is the first thing worth fixing.